Assumptions List
- Stakeholders whose idea “loses” accept the analysis and commit (Desirability)
- Companies upload or connect real revenue, usage, and customer data (Viability / Ethical)
- Teams pay $20 per decision instead of asking ChatGPT for free (Viability)
- Projections from company data are directionally right (Feasibility)
- Teams open a tool mid-meeting instead of deferring to the senior voice (Desirability)
- A PM can go from prompt to analysis in under 10 minutes (Usability)
- Readers interpret ranges and risk correctly, not as certainty (Usability)
- Teams come back months later to log actual outcomes (Desirability)
- The self-organizing database classifies messy uploads correctly (Feasibility)
- PMs face 2+ contested decisions a month (Desirability)
- Jira, Linear, Stripe, Amplitude, etc. integrations are buildable soon (Feasibility)
- Leaders won’t use Cookin’ to rubber-stamp a decision already made (Ethical)
Assumptions Map
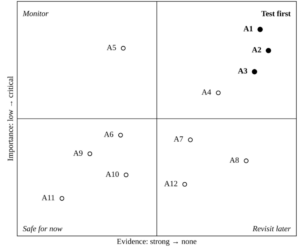 (Not sure why this is so blurry when uploaded!)
Test Card 1
A1: Will the losing side commit?
Method: Prototype test on v0 (the Kitchen)
- We believe stakeholders will commit to a direction once they see Cookin’s analysis, even when it favors someone else’s idea.
- To verify, 5 teams of 3-4 (PM and eng/design/ sales) bring a real open disagreement to a 45-minute session. Each person privately writes their pick and confidence (1-5). The team enters the options into the Kitchen, reads the result together, then re-rates privately.
- We measure teams that decide in the session; “losing” participants who rate the analysis fair (4+ of 5) and say they can commit.
- We are right if 3 of 5 teams decide and 60%+ of losing participants rate it fair.
Test Card 2
A2: Will companies hand over real data?
Method: Concierge test
- We believe PMs will share real internal data (billing, usage, support) to get a decision analyzed.
- To verify, offer 15 PMs at 51-1,000-person SaaS companies a free decision memo on a live decision. They send exports; we run the analysis by hand (Kitchen behind the scenes) and deliver in 48 hours.
- We measure who actually sends real, non-dummy data within 7 days, and what blocked the rest (security review, legal, no access).
- We are right if 5 of 15 send real data and 3 of those needed no security review.
Test Card 3
A3: Will teams pay over a free chatbot?
Method: Fake door price test
- We believe product teams will pay $20 per simulated decision.
- To verify, drive ~300 target visitors (LinkedIn, 2 PM Slack communities, ~$100 ads) to the page. “Pay $20 & run simulation” shows the existing “not charged yet” message, then one question: “What would you have used instead?” A second link shows $60/month to compare models.
- We measure visitor → pay-click rate per price; share of clickers at 51+ person companies; answers to “instead.”
- We are right if 5%+ of visitors click pay (10+ clicks) and under half say they’d just use ChatGPT.